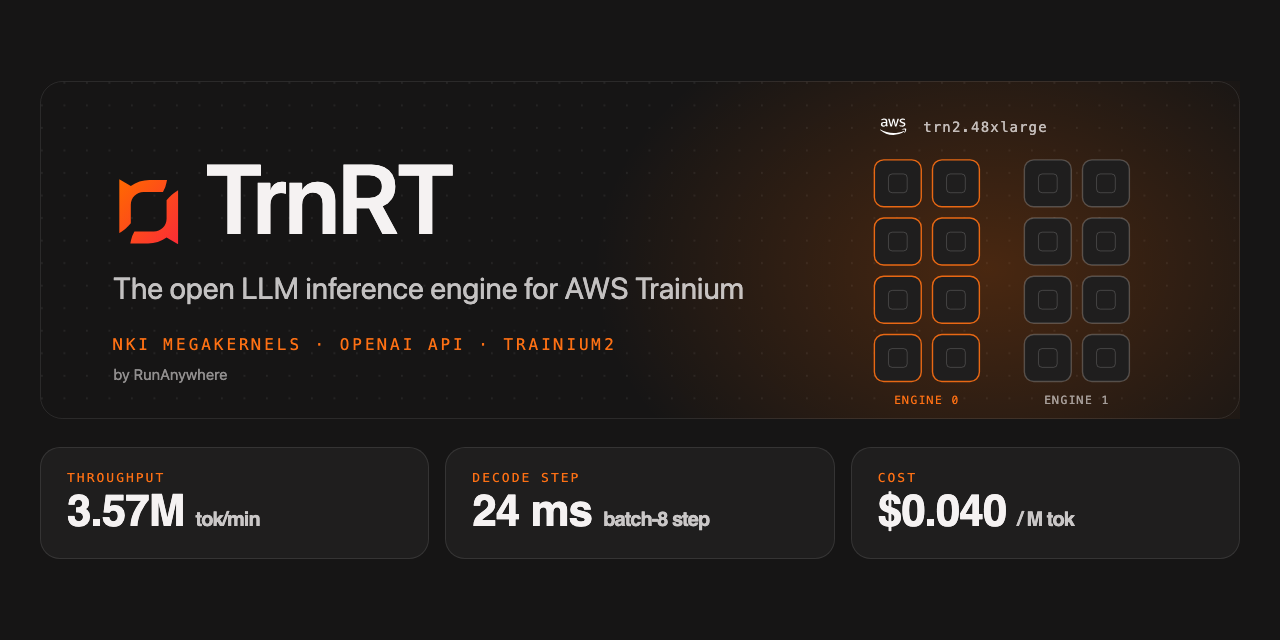
TrnRT is an open-source inference engine serving GLM-5.3-Flash on a single AWS Trainium2 instance. It uses NKI megakernels to handle decode operations and supports a one-million token context window. The setup requires a separate x86_64 host to compile graphs before loading them onto the accelerator.
This is only useful if you already have access to Trainium2 hardware and are running GLM-5.3-Flash. The compile step takes hours and is not done on the serving box, which adds significant operational overhead. It is not a general-purpose LLM server for mainstream GPUs or other model families yet.
more: https://github.com/RunanywhereAI/trnrt
my other side: ivo.blogspot.com


Leave a Reply